What the Architecture Covers
Ingestion
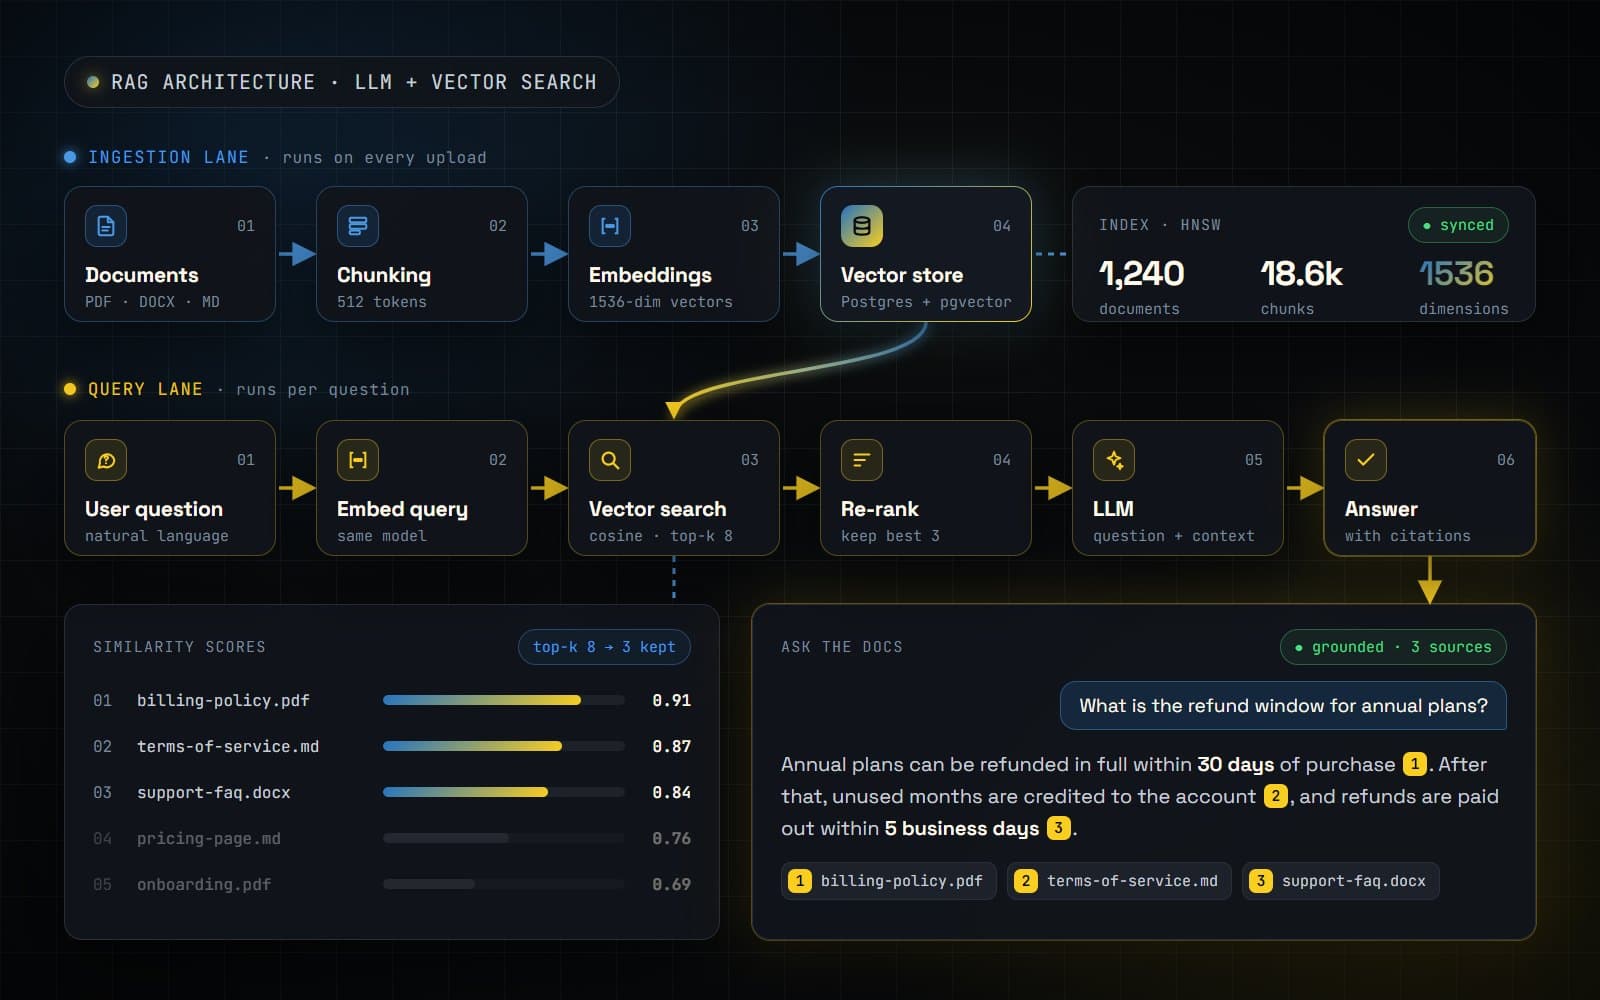
PDFs, docs and web pages parsed, cleaned and split into overlapping chunks with metadata.
Embeddings and vector store
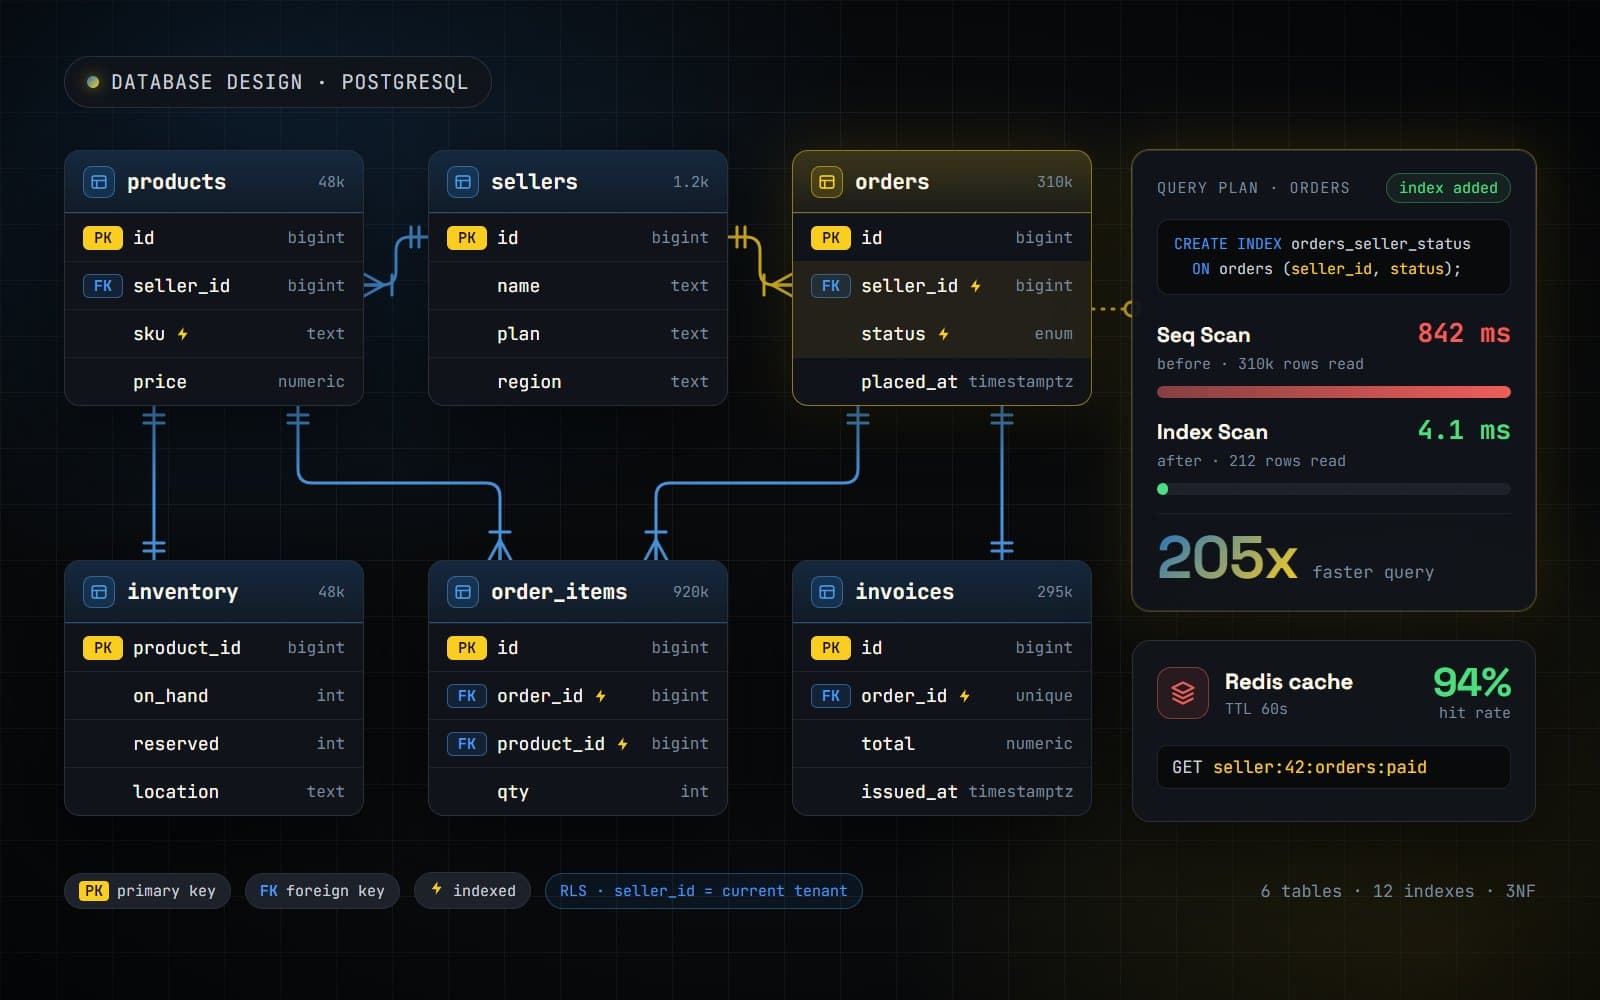
Chunks embedded and stored in PostgreSQL with pgvector, filterable by source, date or team.
Retrieval
Hybrid keyword and vector search returns the top passages, then a re-ranking step keeps the most relevant.
Grounded generation
The LLM answers only from retrieved context and cites each source, so answers can be checked.
Evaluation
Test questions measure retrieval quality and answer accuracy before and after every change.
Cost and guardrails
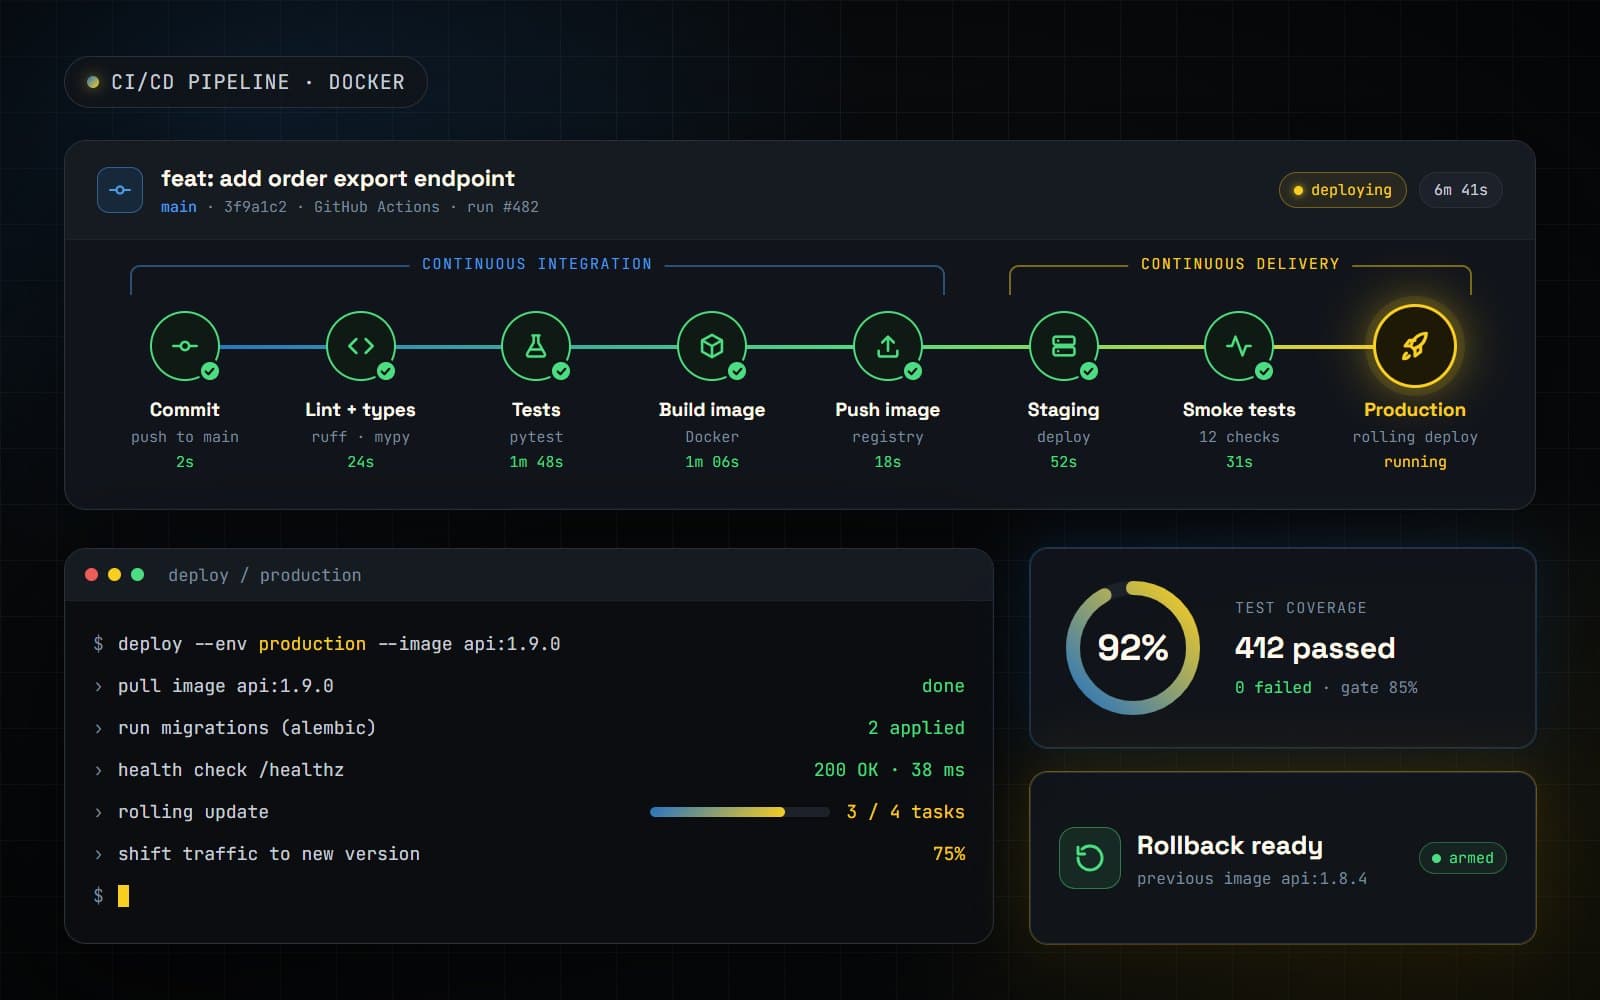
Caching, token budgets and fallbacks keep responses fast, affordable and safe.
Tools & Stack
- Python
- FastAPI
- OpenAI
- Claude
- Embeddings
- pgvector
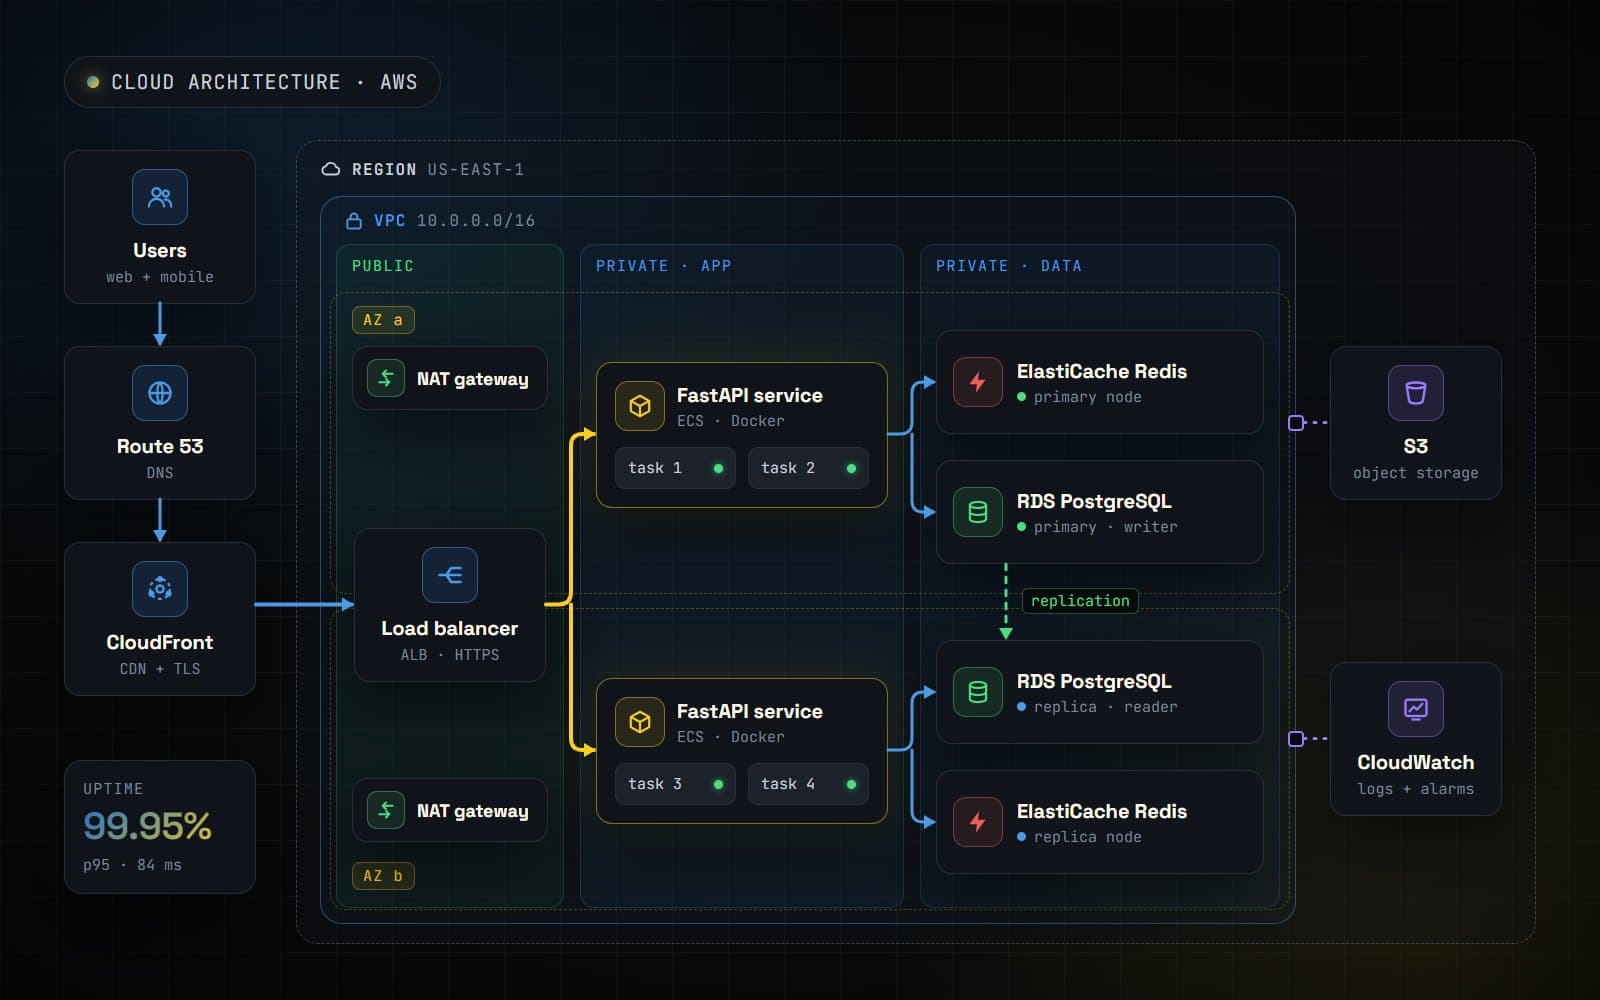
- PostgreSQL
In Practice
This blueprint is part of my AI workflow automation & integration service. Tell me about your system on Upwork and I'll propose the right setup, timeline and cost.